Viewing, Annotating, and Searching PDF Text in a .NET Web App: A Practical Guide
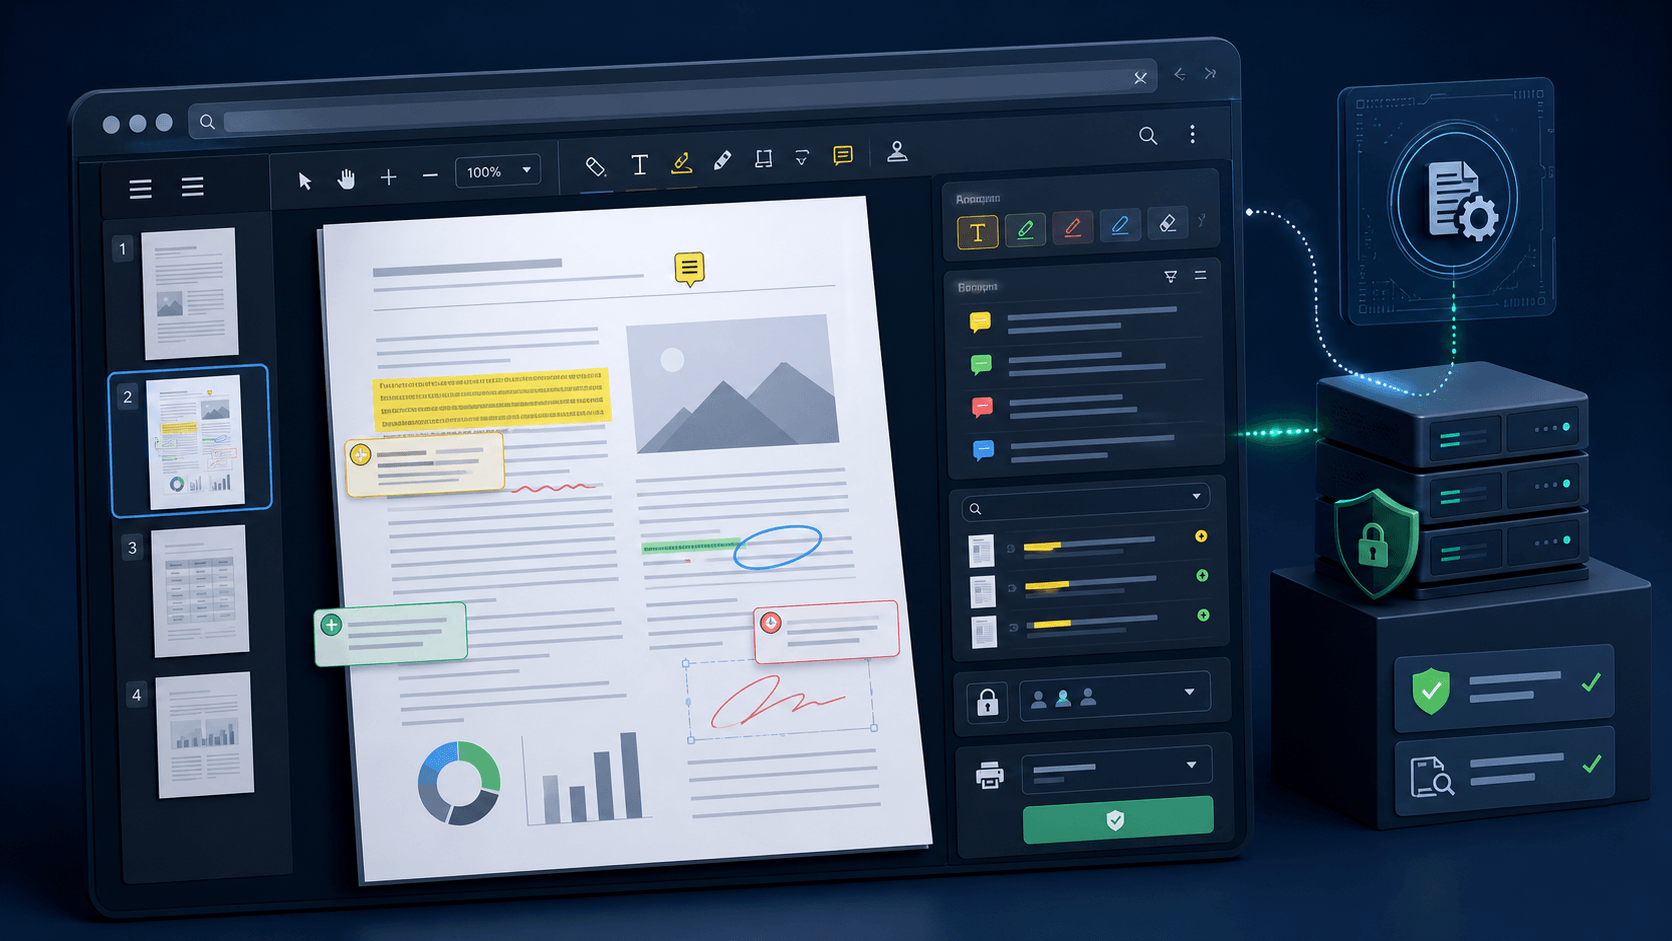
If users need to view PDFs and add review markup without leaving the browser, Doconut provides a self-hosted viewer plus optional Annotation and Search plugins. Search works only with the PDF’s existing text layer; Doconut does not edit PDF content or perform OCR.
In the sections that follow we’ll discuss the overall architecture, annotation and highlighting, text-layer search, and the application controls required around the viewer.
Where PDF Viewing, Annotation, and Search Fit in .NET Apps
Enterprise document‑centric solutions—whether a DMS, a CRM portal, or a legal‑tech review platform—must satisfy three competing demands:
- User experience – reviewers expect a fluid, browser‑based UI that feels like a desktop PDF editor.
- Security & compliance – documents often contain confidential data that cannot be sent to third‑party services.
- Scalability – a single API call may need to serve hundreds of concurrent users across multiple regions.
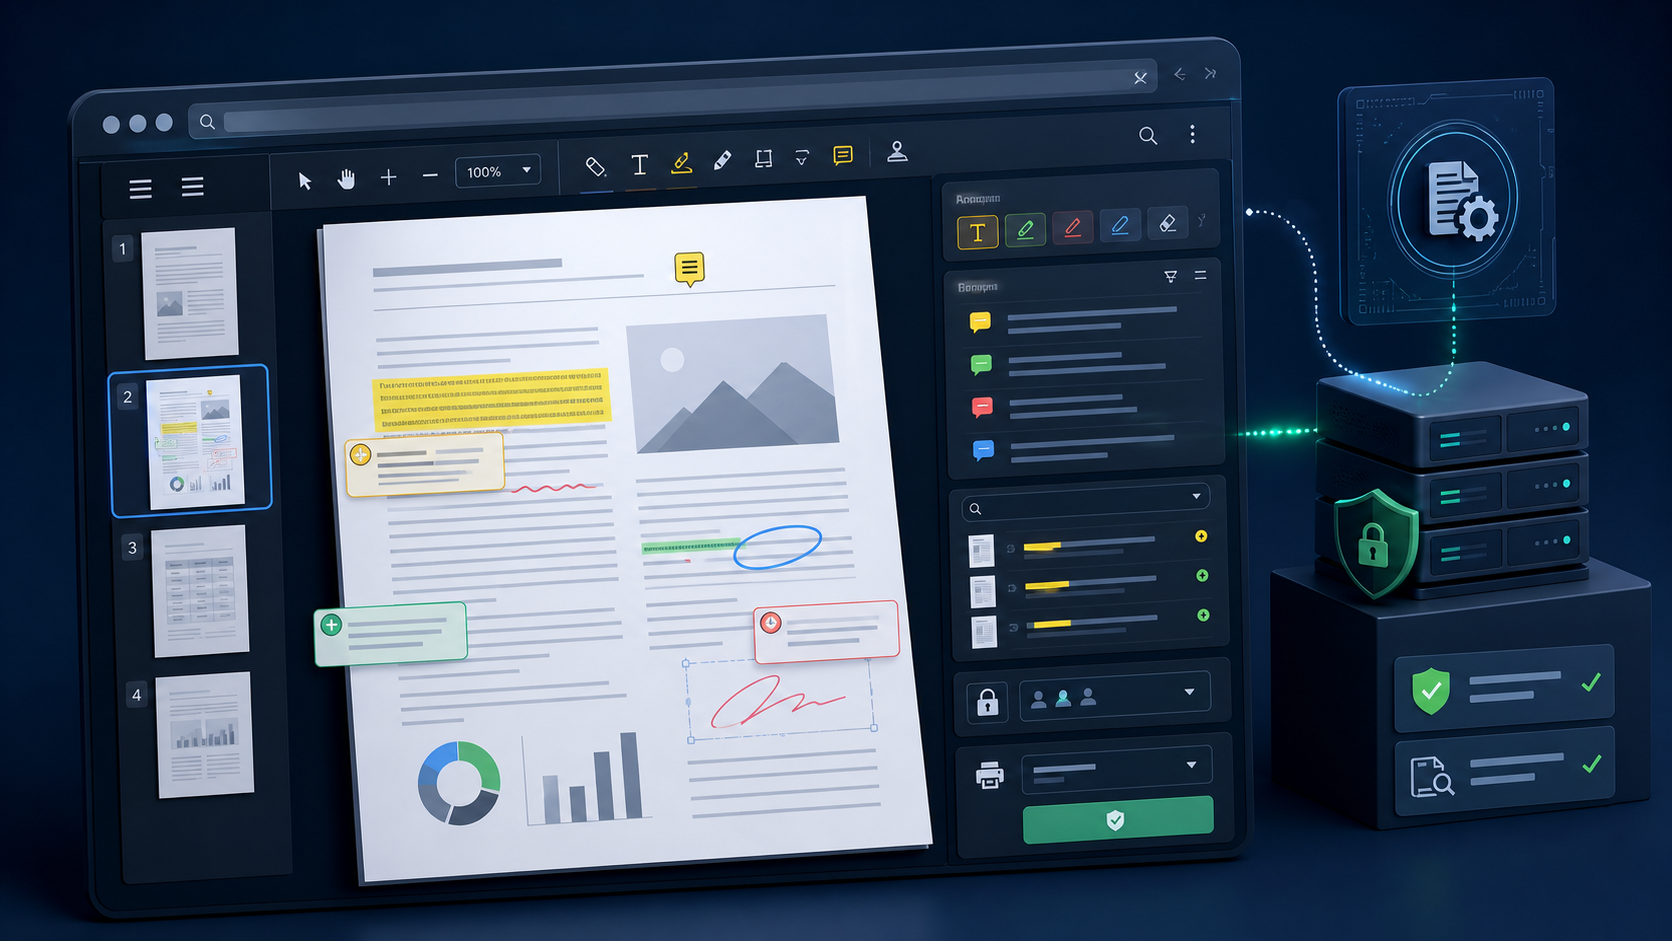
Doconut meets all three with a single library that runs server‑side (so the document never leaves your infrastructure) while delivering rendered content to supported web browsers. Doconut renders supported PDFs, Office files, and CAD drawings on the customer’s server. Annotation is available through the separately released Annotation plugin and does not edit underlying document content.
Key advantages for senior developers and architects
| Benefit | What it means for your solution |
|---|---|
| HTML5/JavaScript UI | The viewer runs in the browser without requiring ActiveX or proprietary PDF plug‑ins. |
| Application-owned permissions | The surrounding application controls users, roles, and access; Doconut has no print-control feature. |
| Text-layer search | The Search plugin searches existing text and does not OCR scanned images. |
| Unified API surface | The same Viewer class handles opening, annotating and searching PDFs. |
By centralising these capabilities, you reduce the amount of custom code you have to write, maintain and audit—an important consideration for regulated industries such as healthcare, finance and legal tech.
Enabling Annotations and Highlights in the Doconut Viewer
The Annotation Plugin is a released optional plugin that must be licensed and integrated separately from the viewer. The typical workflow consists of four logical steps:
- Register the supported Doconut integration – Configure the ASP.NET Core pipeline and browser resources according to the official documentation for your package version.
- Create a
Viewerinstance – In a scoped service or controller, instantiate theViewerobject, passing any required services such as caching and HTTP context accessors. - Open the PDF and obtain a document token – Call the viewer’s document‑opening method, supplying the file path (or stream) and any rendering options (e.g., image resolution). The method returns a unique token that identifies the session‑specific document.
- Work with the annotation manager – Retrieve an annotation manager for the page you want to modify, add a highlight or comment object, then persist the resulting XML back to the server using the viewer’s save method.
The front end loads the viewer with the opaque token and exposes the annotation tools supported by the optional plugin. The application remains responsible for authorization, persistence, and audit logging.
Adding Text-Layer Search with the Search Plugin
A searchable PDF is essential for any knowledge‑intensive portal. Doconut’s Search Plugin searches a document’s existing text layer. It does not perform OCR, so image-only scanned files remain unsearchable unless another part of the application creates a text layer first.
To expose search functionality to the client you typically:
- Confirm that the PDF has a text layer – Doconut Search requires existing searchable text.
- Expose a search endpoint – Implement a lightweight API method that receives a token and a query string, forwards the request to the viewer’s search routine, and returns the matching page numbers and highlight coordinates.
- Display results in the UI – The viewer highlights the matches automatically; the front‑end can provide navigation controls (next/previous) without a full page reload.
Because annotations are stored as XML, search highlights overlay cleanly on top of existing markup, giving reviewers full context while they add comments.
Integrating PDF Viewing and Review into an Application API Layer
Enterprises often expose document functionality through a RESTful API that sits behind authentication, role‑based access control and audit logging. Use the supported .NET server API for viewer, annotation, and search operations, and keep authentication, authorization, logging, and any printing policy in the surrounding application.
A recommended pattern is to encapsulate all viewer interactions inside a DocumentService class. The service can validate caller permissions, open documents, add annotations through the plugin, and run searches against existing text layers. Controllers then call the service methods, keeping the controller code thin and focused on HTTP concerns.
Key points for a secure, scalable implementation:
- Per‑user token storage – Store the document token in a secure cache (e.g., Redis) tied to the user’s session.
- Permission checks – Enforce business rules before any viewer operation.
- Stateless endpoints – Each request includes the token, allowing the service to be horizontally scaled.
- Audit logging – Record annotation and search actions for compliance reporting.
Conclusion
Doconut provides self-hosted PDF viewing with optional annotation and text-layer search plugins. It does not modify PDF content or perform OCR. By following the patterns above you can deliver a secure, high‑performance PDF review experience that scales to enterprise workloads.
Ready to evaluate PDF viewing and review markup in your .NET web application? Request Doconut’s 30-day temporary evaluation license and test the viewer, Annotation plugin, and text-layer Search plugin with representative PDFs.